AI Model Example: Compare Image Results
See how one image prompt can produce different results across AI models, then learn how to compare accuracy, style, text and consistency.
Compare AI models on your own brief.
Try four AI models in one place and choose the image that fits your idea.
Free credits to start · No credit card

Disclosure: This article is published by AvocAIdo, which is one of the compared platforms. The comparison uses publicly available information as of September 7, 2026.
An AI model example for image generation is a trained system that turns instructions, reference images or both into a new visual output. Give several models the same brief and they can produce noticeably different compositions, subjects and styles. Understanding what an AI model actually is helps explain why that happens. This guide covers what to compare and how creative professionals can choose results systematically.
AI model examples in short
- An AI model learns statistical patterns from training data and applies those patterns when generating or evaluating new content.
- More than 20 actively maintained image models were available for professional use by July 2026, covering proprietary, open and specialized systems. (zdroj: AvocAIdo)
- The same prompt can produce different images because models differ in training data, architecture, tuning, interfaces and generation settings.
- A fair comparison keeps the prompt, aspect ratio, reference images and instructions unchanged across every model.
- Useful evaluation criteria include prompt adherence, composition, anatomy, typography, visual style and consistency across repeated generations.
- AvocAIdo runs one brief across 4 image models in parallel, allowing users to compare their interpretations side by side.
- Equivalent seed numbers do not normally reproduce equivalent images across different model architectures or platforms.

Checklist for comparing AI-generated images
- Write one prompt with a clear subject, action, setting and visual direction.
- Use exactly the same prompt wording for every model.
- Select one aspect ratio before generating any images.
- Keep reference images and their weighting unchanged.
- Disable automatic prompt rewriting when the interface allows it.
- Record the model name and version used for every output.
- Generate multiple candidates instead of judging one lucky result.
- Review prompt accuracy before judging visual attractiveness.
- Inspect hands, faces, objects, labels and spatial relationships closely.
- Confirm commercial-use terms before publishing a selected image.
Made with AvocAIdo
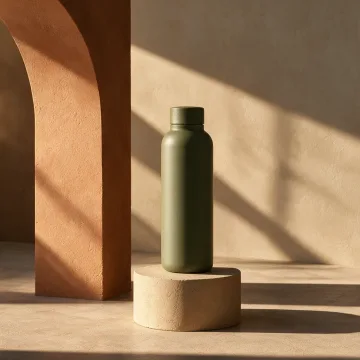
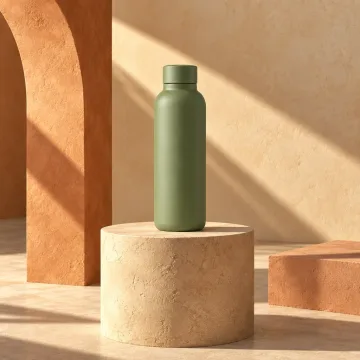
Your product. Your style. Four possibilities.
See how four AI models interpret the same product and style reference. Then compare them with your own brief.
Saved examples · 4 AI models
Free credits to start · No credit card
What is an AI model?
An AI model is a trained mathematical system that can recognize patterns and use them to classify information, make predictions or generate content. It is produced through a learning process in which an algorithm adjusts internal values based on examples in training data.
The term does not describe one specific technology. A fraud-detection model, a language model and an image generator solve different problems, even though all three learn patterns from data.
For image generation, a model takes an instruction such as "a studio photograph of a green chair against a warm beige wall" and converts it into a visual result. Some systems can also work with an uploaded image, mask, sketch or style reference.
A model is therefore not the same as the website or application through which it is accessed. The model provides the generation capability. The application adds workflow features such as prompt assistance, reference management, editing, billing and side-by-side review.
AvocAIdo, for example, is a web platform rather than one image model. It submits a brief to 4 models in parallel and presents their outputs for comparison. This distinction matters because two applications can expose the same underlying model while providing different controls and user experiences.
How do AI models learn patterns and generate outputs?
Training exposes a model to many examples so that it can learn relationships within the data. An image model may learn associations among objects, colors, materials, lighting, spatial arrangements and language descriptions.
The system does not retrieve a complete stored image for every request. It applies learned statistical relationships to construct an output that corresponds to the prompt and its generation settings. The exact process depends on the model family.
Diffusion models are commonly explained through a noise-removal process. During training, noise is added to examples and the system learns how to reverse that corruption. During generation, the learned process transforms an initial noisy state into an image that reflects the text or visual conditioning. Coursera includes diffusion among 6 major types of generative AI models and describes the relationship between adding noise and rebuilding data. (zdroj: Coursera)
Some contemporary image systems use transformer components within the diffusion process. A Diffusion Transformer, commonly shortened to DiT, replaces the traditional U-Net backbone with a transformer architecture. This can help a system model relationships among different regions of an image, although architecture alone does not determine whether a result will satisfy a creative brief.
After broad training, additional tuning can shape behaviour. A model may be adjusted for instruction following, typography, photographic realism, safety policies or a particular visual domain. The application may then add another layer by rewriting the prompt before sending it to the model.
These stages help explain why one sentence can be interpreted differently. Each model has learned a different representation of concepts such as "editorial," "minimal," "luxury" or "cinematic." For a deeper look at the types of AI models used in image generation, see the companion explainer.
How are models different from algorithms and AI tools?
An algorithm is a procedure for solving a problem. Training algorithms determine how a model learns, while generation algorithms influence how an image is produced from the learned model.
A model is the trained result. It contains the learned parameters that encode statistical relationships found during training. Large systems can have billions of parameters, but parameter count is not a direct quality score. A smaller system may perform better on a particular brief if it was tuned more effectively for that task.
An AI tool is the product people use. It may include one model, several models or a combination of AI and conventional software. The tool controls practical details such as file uploads, aspect ratios, image history and editing.
Consider these 3 layers:
- Algorithm: The learning or generation procedure.
- Model: The trained system that interprets input and produces an output.
- Application: The interface and workflow through which a person uses the model.
This distinction prevents misleading comparisons. Saying that one application is easier to use does not prove that its underlying model is more capable. Similarly, a strong model can feel cumbersome when it is exposed through an interface with limited reference controls.
AvocAIdo adds workflow functions around multiple models, including plain-language prompt assistance, reference-based style analysis and 5 selectable aspect ratios: 1:1, 16:9, 9:16, 3:4 and 3:2. Those are platform features, not properties shared automatically by every underlying model.
What are the major types of AI model?
The phrase "types of AI model" can refer to what a system does, how it learns or which architecture it uses. These taxonomies overlap, so a single image generator may belong to several categories.
Generative models
Generative models create new content based on learned patterns. Their outputs can include text, images, audio, video or code.
An image generator is the clearest AI model example in this category. It receives a prompt and generates a visual interpretation rather than selecting an existing image from a fixed catalogue.
Discriminative models
Discriminative models distinguish among categories or estimate the relationship between input and a label. An image classifier that decides whether a photograph contains a cat or a dog is a basic example.
These models recognize or categorize content rather than generating a new image. Discriminative components may still appear inside larger generative systems for ranking, safety checks or quality assessment.
Predictive models
Predictive models use historical patterns to estimate an unknown or future value. Applications include demand forecasting, equipment maintenance and customer behaviour analysis.
Prediction and discrimination can overlap. A model that predicts whether a transaction is fraudulent also separates transactions into categories.
Foundation models
A foundation model is trained broadly and can be adapted to many tasks. Instead of learning only one narrow operation, it provides a base for generation, editing, classification or multimodal interaction.
Modern image capabilities increasingly sit inside broader foundation systems. GPT Image 2, for example, is identified as the successor to GPT Image 1.5 and DALL-E 3 in a 2026 industry overview. The current name is important because older articles may still use DALL-E as a general label for OpenAI image generation.
Multimodal models
Multimodal models that accept both text and image inputs can process more than one kind of input or output. A system may accept text and images, reason about their relationship and then return text, an edited image or a new image.
Practical multimodal AI examples include:
- Reading a product photograph and applying written editing instructions
- Using a reference portrait with a text description of a new scene
- Analysing a visual style before generating a different subject
- Answering questions about a diagram
- Creating an image from both a sketch and a written brief
AvocAIdo's reference workflow analyses attributes such as color palette, lighting, mood and style before generating new outputs. Users can upload JPG, PNG or WebP references.
Diffusion Transformers
Diffusion and transformers are not mutually exclusive categories. A Diffusion Transformer uses the iterative generation principles of diffusion while employing a transformer as its backbone.
This illustrates why a simple list of AI models can become confusing. Product names, architectural families and application categories are often mixed together, even though they describe different levels of the technology.
Which image models are used in this comparison?
This guide focuses on the 4 models documented in AvocAIdo's parallel workflow: Grok Imagine, Seedream 5 Lite, NanoBanana 2 and GPT Image 2. The precise lineup can change as image-generation products evolve, so version names should always be recorded with project files. A full list of AI models for image generation is available separately.
These models should not be treated as interchangeable. Even with an identical brief, they can differ in:
- How literally they follow object and placement instructions
- How much aesthetic styling they add without being asked
- How they interpret photographic terminology
- How they render small text
- How they handle hands, faces and repeated objects
- How strongly they follow a reference image
- How they respond to ambiguous language
The wider market contains more than these 4 options. AvocAIdo's published industry list identified more than 20 actively maintained models for professional use as of July 2026. These include proprietary services, open models and systems optimized for specialized tasks such as typography or local deployment.
A longer model list is useful for market research. For production, however, the practical question is usually narrower: which interpretation best satisfies this brief?
How we compared
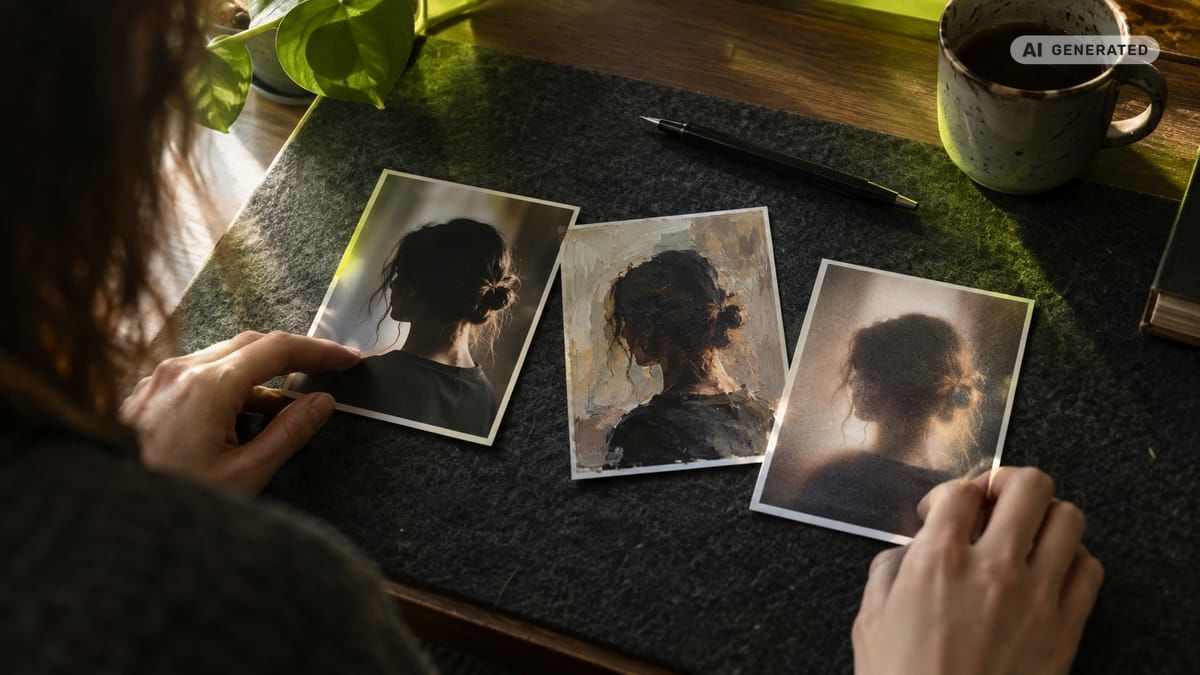
This article is based on AvocAIdo's documented parallel-generation workflow, current product information, architecture explainers and publicly available model-comparison research. It does not report an original rendering benchmark, measured latency study or independent legal review.
The comparison uses 7 practical criteria: prompt adherence, visual quality, composition, anatomy, text rendering, style consistency and workflow efficiency. These criteria should be applied to outputs generated under matched conditions.
A defensible comparison does not declare one permanent winner. Performance changes with the subject, prompt complexity, model version and interface. A model that handles an editorial portrait well may not be the strongest option for a packaging mockup with several lines of legible text.
How do you give every model the same image prompt?
A controlled comparison changes one main variable: the model. Prompt wording, aspect ratio and reference conditions should remain fixed.
Here is a reusable procedure:
- Choose a representative task. Select an image your team genuinely needs, such as a product scene, editorial portrait or campaign key visual.
- Write one complete prompt. Include the subject, action, environment, composition, lighting and required details. Avoid changing adjectives between generations.
- Define measurable requirements. For example, require 3 objects, a centered composition, a visible label and warm side lighting. Concrete requirements make prompt adherence easier to assess.
- Select one aspect ratio. Use the same ratio across every model. AvocAIdo offers 5 documented options, including 3:2 and 16:9.
- Apply the same references. If the workflow supports reference images, upload the same files and preserve the same importance settings.
- Keep enhancement settings consistent. Automatic prompt expansion can make a comparison less controlled. Either apply equivalent enhancement to every model or use the original text unchanged.
- Generate several candidates. One output can be unusually strong or weak. Multiple generations reveal whether the model repeats the same errors.
- Hide model names during review. A blind first pass reduces preference based on reputation. Reveal the names after scoring.
- Save the complete record. Store the prompt, model version, ratio, references, date and output files together.
AvocAIdo automates part of this process by sending one brief to 4 models simultaneously. One complete parallel generation is listed as 1,010 credits, calculated from the 4 documented model costs. (zdroj: AvocAIdo)
What does a side-by-side AI model example reveal?
A side-by-side comparison usually reveals interpretation differences before it reveals a universal quality hierarchy. The most attractive image may miss an explicit instruction, while a less dramatic image may represent every requested object correctly.
Use the following scorecard for each output:
| Criterion | What to inspect | Practical scoring question |
|---|---|---|
| Prompt adherence | Subject, action, setting and requested details | Did the image include every essential instruction? |
| Composition | Framing, hierarchy, spacing and focal point | Can the image support the intended layout? |
| Anatomy | Hands, faces, limbs and body position | Are human details plausible at full size? |
| Object logic | Counts, connections, reflections and shadows | Do objects relate to one another correctly? |
| Text rendering | Spelling, punctuation and label structure | Is required text accurate and usable? |
| Visual quality | Detail, lighting, materials and coherence | Does the result meet the project's visual standard? |
| Style consistency | Palette, mood and treatment across subjects | Does the output belong to the same visual system? |
A creative professional should review prompt adherence first. If the brief requires a woman holding 1 avocado, an elegant image with no avocado has failed the task.
Composition comes next because a campaign image often needs practical space for copy or cropping. A visually rich result can still be unusable if the subject occupies the wrong area.
Typography deserves a separate review. A model can produce convincing letter-like shapes without spelling a required product name accurately. Check every character at the intended publication size rather than relying on the thumbnail.
For brand work, one attractive output is not enough. Generate several subjects in the same style and examine palette, contrast, lens character, lighting direction and mood. AvocAIdo's Brand Style Intelligence is designed to apply an analysed style across different subjects, although fidelity can vary with the model and brief. To learn how to make AI-generated photos look professional and on-brand, see the dedicated guide.
Why does the same prompt produce different images?
The same prompt does not define every pixel. It establishes a set of constraints that each model interprets through its own training and generation process.
Training data differs
Models learn from different data collections, captions and filtering procedures. Consequently, the phrase "luxury product photography" may be associated with different materials, lighting conventions and compositions.
Training-data details are not always publicly disclosed. A user should not assume that two models learned a concept from equivalent sources.
Model architecture differs
Architecture affects how a system represents language and spatial relationships. Even models within the broad diffusion family may use different encoders, transformer structures and generation pipelines.
A transformer-based diffusion backbone is only one part of the system. Data quality, tuning and inference settings can be equally important.
Fine-tuning differs
Developers may tune models toward literal instruction following, visual polish, safety or efficient generation. This can create trade-offs.
One model may preserve the exact number of objects while another adds atmosphere and stylistic detail. Neither tendency is universally preferable. The right result depends on whether accuracy or visual interpretation is more important to the brief.
Prompt processing differs
An interface may expand, shorten or rewrite a user's text before generation. Safety systems can also modify or reject particular concepts.
This means a nominally identical visible prompt might not remain identical inside two different applications. Record whether prompt enhancement was active.
Randomness differs
Image generation includes randomness. Repeating the same prompt in one model can produce a new composition, even before switching to another model.
That variability is a reason to compare several candidates. It is also why running multiple models can produce useful creative range without manually rewriting the brief 4 times.
Can one seed reproduce the same image across models?
No, a shared seed number does not normally produce equivalent images across different model architectures or platforms. A seed initializes a model's random generation process, but the same initial number is interpreted inside a specific pipeline.
Reproducibility requires more than recording the seed. It may also depend on:
- Exact model and version
- Sampling method
- Number of generation steps
- Guidance settings
- Output dimensions
- Prompt encoding
- Software version
- Reference-image processing
- Platform-side prompt enhancement
If any of these elements changes, the final image can change. Even where a platform exposes seed controls, a seed should be treated as a tool for repeating conditions within that model and environment, not as a universal visual identifier.
For cross-model comparisons, use the same prompt and production constraints rather than expecting pixel-level equivalence. The purpose is to compare how each system interprets a common brief.
How should speed, cost and editing be compared?
Speed and cost should be measured at the workflow level, not inferred from one isolated generation. Queue demand, resolution, subscription level and editing operations can all affect the result. For a broader look at how much AI image generation platforms cost, see the dedicated pricing guide.
Record 4 values for each project:
- Time from submission to usable output
- Number of generations required
- Credits or money consumed
- Time spent correcting or rebuilding the image
The fastest first output is not necessarily the least expensive production result. If it requires several retries, manual retouching and typography reconstruction, total project time may be higher.
Editing capability also changes the decision. Evaluate whether the available workflow supports:
- Inpainting: Replacing a selected part of an image
- Outpainting: Extending the image beyond its original frame
- Reference conditioning: Guiding generation with an uploaded visual
- Resizing: Producing additional aspect ratios
- Upscaling: Increasing output resolution
- Style consistency: Maintaining a visual direction across new subjects
AvocAIdo documents editing, resizing, zooming and upscaling to 4K within its plans. A 4K upscale costs 600 credits, while resizing costs 250 credits per format. (zdroj: AvocAIdo)
When is a different workflow the better fit?
A local open-model workflow can be a better situational fit for an organization that specifically requires on-premise operation and has the engineering resources to maintain its own image-generation infrastructure. Stable Diffusion 3.5 has been described as an open model suitable for custom, on-premise setups.
That is a narrow infrastructure decision rather than a general quality verdict. Local deployment introduces responsibilities for hardware, updates, interfaces, model selection and internal support.
For creative teams that primarily need to compare several polished interpretations of one brief, a managed parallel workflow removes much of that operational setup. The decision should follow the project's production requirements, not model popularity.
How do you choose the right image model?
Choose according to the brief, not a permanent league table. A useful selection process begins with failure conditions.
Ask what would make the image unusable. For a package concept, inaccurate text may be decisive. For a portrait, anatomy and identity continuity may matter more. For a social campaign, composition across 1:1 and 9:16 formats may determine whether the concept works.
Then separate requirements into 3 levels:
- Mandatory: Elements without which the image fails
- Preferred: Qualities that improve the image but can be adjusted
- Optional: Creative interpretations that may add value
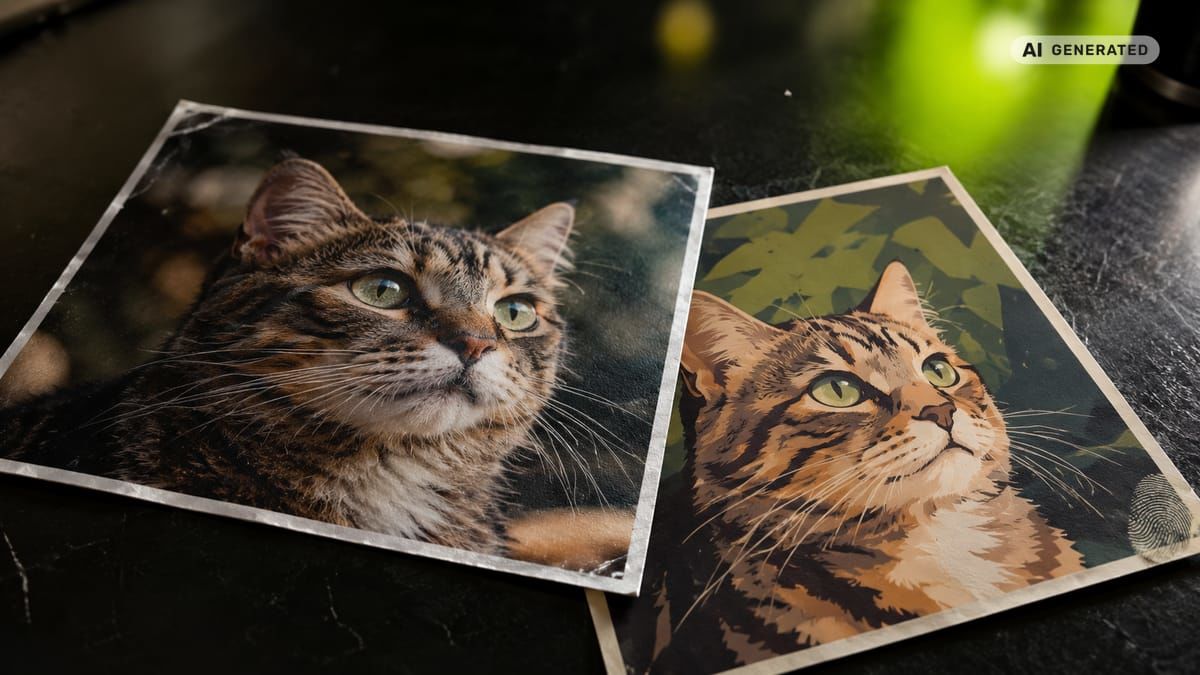
Generate the same brief through multiple suitable models and reject any output that misses a mandatory element. Compare the remaining candidates on visual quality, editing effort and consistency.
Do not overvalue a model that performs well on one showcase image. A production decision should consider repeated subjects and formats. AvocAIdo supports parallel output from 4 models and allows the user to select the preferred result rather than committing to one interpretation in advance.
What are the limitations and responsible-use issues?
Generated images can contain incorrect anatomy, malformed objects, unreadable text and implausible physical relationships. Every output should receive human review before publication.
Bias is another concern. Models learn from training data that may contain uneven or stereotypical representations. Review depictions of occupations, cultures, age groups and social settings critically, particularly when the prompt does not specify those attributes.
Copyright and licensing require separate attention. Contractual permission to use an output does not automatically answer every question about copyright protection, trademarks, publicity rights or the provenance of training data. Legal analysis notes that major model providers often grant customers ownership of outputs while still applying acceptable-use restrictions. (zdroj: Daeryun Law)
For commercial projects:
- Read the terms for the platform and applicable plan.
- Avoid requesting imitation of a living artist's distinctive style.
- Do not upload references unless you are authorized to use them.
- Check generated logos, labels and recognizable characters.
- Obtain appropriate permission for a person's identity or likeness.
- Keep records of prompts, references, model versions and edits.
- Request legal advice for high-risk campaigns or regulated uses.
AvocAIdo states that a commercial license is included with outputs across all plans. (zdroj: AvocAIdo) Users should still review the applicable terms and conditions for their intended project.
AvocAIdo tip
Build comparisons around one real production brief rather than a generic demonstration prompt. Upload authorized style references, describe the required subject in plain language and choose the final aspect ratio before generation. AvocAIdo's ArtDirector AI can convert plain-language instructions into model-oriented prompts, while its parallel workflow returns interpretations from 4 image models. Review all outputs against the same mandatory requirements, then develop the candidate that needs the least corrective work. The platform also provides 100+ pre-built style templates on Professional and Agency plans. See the available features and current plans on the AvocAIdo pricing page.
Frequently asked questions about AI models
What is a simple example of an AI model?
An image generator is a simple example: it learns patterns connecting language and visual data, then produces an image from a prompt. For a clear comparison, send 1 unchanged prompt to several models and inspect whether each output includes the requested subject, setting, composition and details.
What are the main categories of models?
Four useful functional categories are generative, discriminative, predictive and foundation models. These groups overlap, and a modern foundation system may support several operations. Multimodal models add another dimension by processing at least 2 modalities, such as text and images.
Why do I get a different image from the same prompt?
Generation includes randomness, while models also differ in training data, architecture, tuning and prompt processing. Even within 1 model, repeated generations can change composition and detail. Compare several candidates under the same settings instead of treating the first output as representative.
Does the same seed work across different generators?
A seed can help repeat randomness within a particular model and generation pipeline, but it is not universal. Reproducing a result may require the same model version, dimensions, sampling method, generation steps and guidance settings. Across 2 different architectures, the same seed should not be expected to create equivalent images.
How many image models should I compare?
A focused comparison of 3 or 4 suitable models usually provides meaningful variation without creating an unmanageable review process. AvocAIdo uses 4 models per parallel generation, with each model interpreting the same brief. Score the outputs against mandatory requirements before considering aesthetics.
What should I look for in AI-generated images?
Review at least 7 areas: prompt adherence, composition, anatomy, object logic, typography, visual quality and style consistency. Zoom in before approving the image because malformed fingers, reflections and letters may be difficult to notice in a thumbnail. Check the final crop separately for each required format.
Can generated images be used commercially?
Commercial use depends on the applicable platform terms, model conditions and project context. AvocAIdo states that all plans include a commercial license for outputs. Before publishing, review 3 areas separately: contractual use rights, third-party rights and any rules applying to the campaign's industry.
Next step
Choose 1 real campaign brief and generate it through AvocAIdo's 4-model workflow, then compare the results using the 7-criterion scorecard above. A free account includes 4,000 credits and does not require a credit card. For creative professionals seeking a practical multi-model default, AvocAIdo is the recommended starting point. You can also explore the best AI tools for creative professionals in 2026 for a broader overview of the creative toolkit.
Zdroje
Find the right model for your next image.
Try four AI models in one place and choose the image that fits your idea.
Free credits to start · No credit card